Vinay KumarChief Product and Technology Officer at DigitalOcean
Yesterday we launched Managed Agents on DigitalOcean in a private preview. I want to put it in the context of a conviction I've held for a while.
The first generation of clouds was built compute-first. AWS started with EC2, and everything else — storage, networking, databases, even AI services — layered on top. That architecture won the last twenty years.
I fundamentally believe the new AI-native cloud starts token-first. Everything else, including "compute", is a means to enhance the intelligence generated by tokens. Agents are the new interface to the cloud — one that brings tokens and microVMs together under a single abstraction.
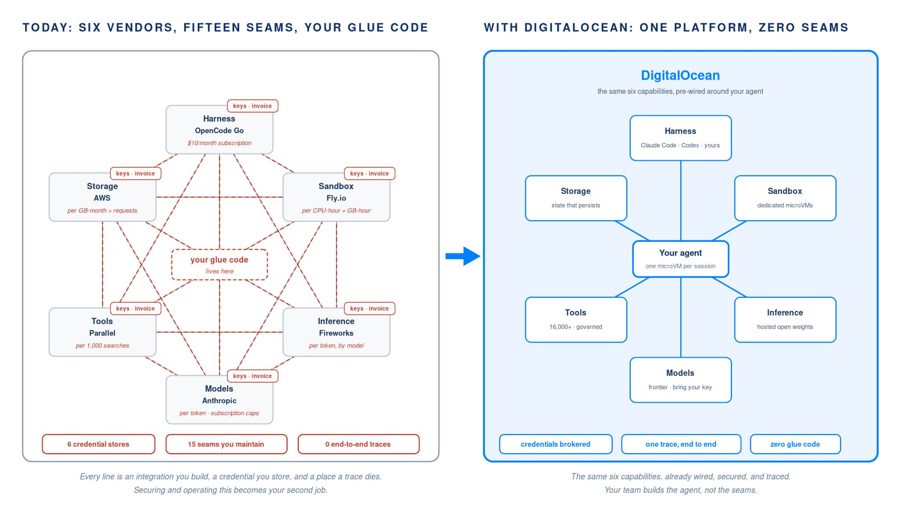
DigitalOcean's Managed Agents Runtime Services (M.A.R.S.) is the first full expression of that construct, and it stands on four fundamental services we've been building deliberately:
Serverless inference — tokens on tap. You consume tokens the way you consume bandwidth. No model hosting, no GPU capacity planning, no idle spend. The meter runs only when your agent thinks.
Firecracker microVM compute — every agent session runs in its own hardware-isolated microVM, starting in under a second and scaling to zero. It's the right compute unit for software that works in bursts rather than runs forever.
Durable sessions — agents that outlive your laptop. Pause and resume in as little as 200 milliseconds with files, processes, and working state intact. Continue from another device, hand off mid-task to a teammate, or fan out to parallel agents without multiplying infrastructure.
Action Gateway — governed access to the outside world. Agents reach GitHub, Jira, Notion, Linear, and Postgres through centrally managed authentication, permissions, human approvals, and audit controls. OAuth credentials are brokered through Secrets Manager and never exposed to the model or the execution environment.
You describe the agent — its harness, tools, and guardrails. Bring Claude Code, Codex CLI, OpenCode, or agents built on LangGraph and CrewAI. No proprietary framework, no lock-in. We run the tokens and the compute underneath.
If you're wondering what to build first, here are ideas you can ship in a weekend:
- A support agent grounded in your docs and past tickets that escalates only what it can't resolve
- A code-review agent that runs on every pull request with full repo context, safely isolated in its own microVM
- A data agent that turns plain-English questions into queries against your managed database
- An ops agent that watches alerts, triages incidents, and drafts the runbook update before you're paged
- A back-office agent that reconciles invoices, chases renewals, and processes intake forms overnight
This is where our cloud investment is going: a next-generation cloud construct built for AI natives, token-first from the ground up.
Request access here: https://lnkd.in/es8gwYnp. And tell me what you'd build.
#DigitalOcean #agents #tokens #microVMs